How to build an AI-powered business application: architecture, cost & timeline
Building an AI application is not simply a matter of connecting a chatbot API to a frontend. Production AI software needs a product model, data architecture, evaluation strategy, security controls, and an interface users can trust.
Last updatedSeptember 16, 2026First published September 6, 2026
CategoryArtificial Intelligence
Reading time8 min read
A practical guide to building an AI business application: production architecture, seven development stages, cost ranges, realistic timelines, and deployment.
What this covers
Production architecture for AI apps, the seven development stages, evaluation strategy, cost drivers, and realistic delivery timelines.
Useful for
Founders, CTOs, and product teams planning an AI build and deciding between an MVP and a full production application.
Architecture
A practical production architecture.
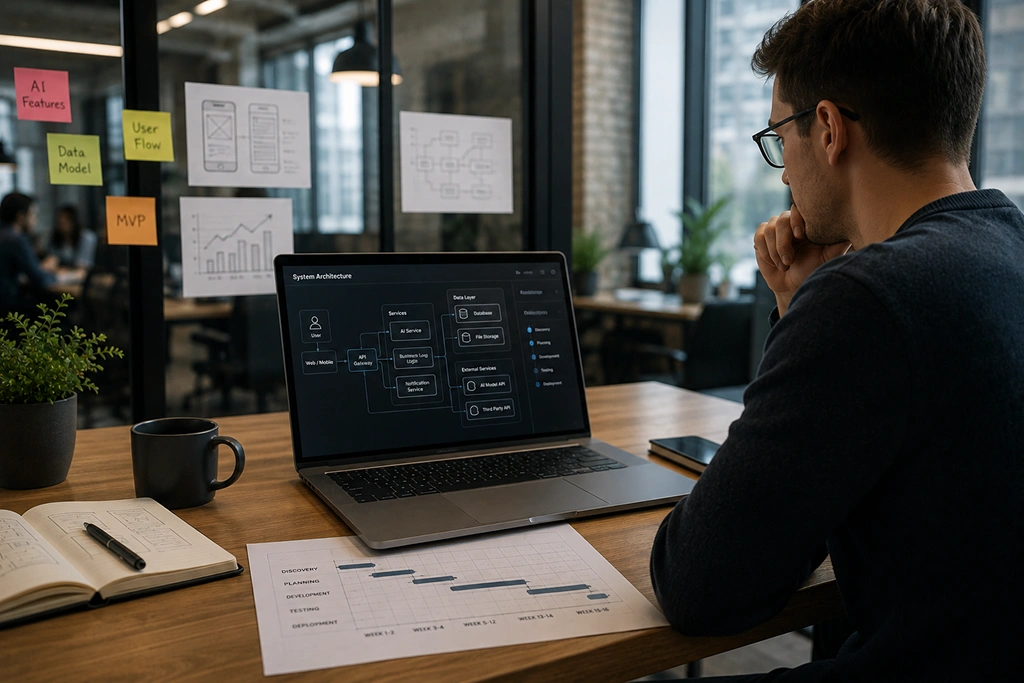
A modern AI application often includes: a web or mobile frontend, an API and backend layer, authentication and authorization, business logic, an AI orchestration layer, a model provider, a retrieval or vector database when needed, an operational database, external integrations, and logging and monitoring. The architecture should keep the AI layer replaceable where practical. Model providers change quickly, so tightly coupling the entire application to one model can create unnecessary technical risk.
Development stages
The seven development stages.
1. Discovery: define users, business outcomes, data, and constraints. 2. UX design: design AI-specific states such as uncertainty, citations, editing, retry, and human review. 3. Architecture: choose models, databases, APIs, and deployment strategy. 4. MVP: build the smallest end-to-end workflow. 5. Evaluation: test quality, safety, latency, and cost. 6. Production: add security, monitoring, analytics, and operational controls. 7. Iteration: improve based on real usage.
Timeline & cost
Timeline and cost expectations.
Across the market, teams planning an AI build should expect a focused AI MVP to take 6–12 weeks and a full production business application 3–6 months. Complex enterprise systems with heavy integrations run longer. Those are useful planning ranges, but they describe the market average for a first AI build — not a fixed rule. At Vordx we commit to a tighter window: a scoped AI MVP ships in 4–8 weeks at $15,000–$40,000, and production applications and multi-system agents in 8–16 weeks at $40,000–$120,000+. The difference is delivery discipline, not optimism. We run a fixed-scope discovery sprint first, so the architecture, evaluation plan, and milestone dates are agreed before build work starts, and the AI layer stays replaceable so model changes never blow up the schedule. The largest cost drivers are engineering scope, integrations, data complexity, UX requirements, security, and testing — not the model API. A cheap prototype can still become an expensive product if the evaluation, observability, and human-review paths were never scoped.
The principle
Build a business application with AI inside.
The key principle is to build a business application with AI inside it, rather than building an AI demo and hoping users find a reason to use it. Start from the workflow that needs improving, then add AI where it genuinely helps.
Data & grounding
Grounding the model on your own data.
A language model knows nothing about your business until you give it context, so data work is usually the larger half of an AI project. The decision that matters most is how you make that context available at request time. For question answering over documents, retrieval-augmented generation remains the default. Documents are split into passages, each passage is converted to an embedding, and those embeddings are stored in a vector database. At query time the system embeds the question, retrieves the closest passages, and passes them to the model as context. The answer is therefore grounded in retrieved text rather than model memory, and you can cite the source passage back to the user. That pipeline has four failure points worth planning for. Chunking sets the size of the retrievable unit, so chunks that are too small lose context and chunks that are too large bury the answer in noise. Embedding choice determines recall, and it is worth testing two or three embedding models against real queries before committing. Metadata filtering matters once the corpus grows, because users almost always want to search a subset such as one product line or their own account. And retrieval quality caps answer quality, which is why measuring retrieval separately from generation usually pays for itself. When the data is structured rather than narrative, skip retrieval. Letting the model emit a parameterized query that your own service executes against a relational database is usually more accurate, cheaper, and easier to audit than summarizing rows into a prompt. Reserve retrieval for unstructured material, and use tool calls for anything that lives in a table. Hybrid systems use both: a router classifies the question, sends structured questions to a database tool, and sends document questions to retrieval. This is more work to build and is usually the right answer once a product has more than one kind of content.
Model strategy
Choosing models and controlling inference cost.
Model choice drives both answer quality and unit economics, and it is rarely a single decision. In practice the useful pattern is a small routing layer in front of two or three models rather than one model for everything. Send routine classification, extraction, and formatting work to a small, fast, inexpensive model. Reserve a frontier model for the requests that genuinely need reasoning, long context, or reliable multi-step output. Routing on task difficulty is one of the highest-leverage cost optimizations available, and it typically reduces spend substantially without a visible drop in user-perceived quality. Four levers actually move the bill. Prompt length dominates, so trim retrieval to the passages that matter rather than passing an entire corpus. Output length dominates on generation tasks, so cap tokens and design outputs for structure rather than prose. Caching removes repeated work, and it pays off immediately wherever users ask similar questions or the same document is processed repeatedly. And batching spreads small requests across a window instead of paying a premium for immediate dispatch. The operational risk to plan for is provider concentration. Building directly against one vendor's API makes it easy to inherit their pricing changes and hard to switch. Keeping a thin internal interface that normalizes requests and responses means a provider swap is a configuration change rather than a rewrite, and it gives you some negotiating room.
Quality & safety
Evaluation, guardrails, and the states your UX must handle.
AI systems fail differently from conventional software, and a passing test suite tells you very little. A deterministic function either returns the right value or it does not; a model returns a plausible answer that is wrong, and the failure is invisible unless you look for it. Build an evaluation set early, before the product is finished. Assemble several dozen real inputs drawn from actual use, including the awkward ones, and record what a correct response looks like. Then score changes against that set every time you touch prompts, models, or retrieval. Without this loop, refactoring becomes a gamble, because there is no way to tell an improvement from a regression. Layered defenses matter more than any single technique. Constrain the output format so a malformed response is rejected at the boundary rather than parsed downstream. Validate retrieved context before using it, and fall back to a clear refusal when retrieval finds nothing relevant. Cap the steps an agent may take and the tools it may call, so a confused loop terminates instead of burning budget. Log prompts, outputs, and tool calls, because without those logs a quality complaint is not diagnosable. And keep a human review path for the consequential decisions, since automation without review just relocates the error. This is also where interface design stops being cosmetic. Users need to see when the system is uncertain, see which sources support an answer, correct it when it is wrong, and understand what happens to their request. Designing those states early is what separates an AI feature people trust from one they quietly stop using.
Operations
Deployment, latency, and what production actually requires.
The build is not the finish line, and teams that treat it that way discover the gap during the pilot. Latency is the first thing users notice. Streaming tokens back to the interface makes a long response feel fast even when total time is unchanged, and it lets people interrupt a response they can already see is going wrong. On the infrastructure side, keep inference calls behind a queue rather than in the request path, so a slow upstream model degrades into a wait instead of a timeout. Cache aggressively, and set explicit timeouts with retry policies that respect rate limits. Observability should be treated as part of the feature. Track latency, token usage, and cost per request, and alert on the rate of fallbacks and refusals rather than only on server errors. A rise in refusals usually means a retrieval regression, and it is far cheaper to catch than a slow drift in answer quality. Tag production traces so you can reproduce a specific bad response rather than reasoning about aggregates. The cost of operating the system is a design input, not a surprise at the end. A feature whose inference cost exceeds its margin needs either cheaper routing, tighter output constraints, or a different product boundary, and that is far easier to decide at the architecture stage than six months after launch.
Before you commit
Failure modes to catch before committing to a build.
Most AI projects that disappoint were compromised by a decision made in week two and discovered in month six. These are the ones worth challenging early. Starting with the technology rather than the workflow. If the goal is stated as building a chatbot, scope is guessing. Naming the specific decision or task the system improves, and the hours it returns, makes the rest of the work decidable. Promising certainty the system cannot deliver. Language models produce plausible output, not verified fact. Where an answer can cause real harm, the honest design is assistance with review rather than autonomous action. Underestimating data preparation. In our experience the data work consumes more calendar time than the engineering, and it cannot be compressed by adding engineers because it is mostly waiting on people who own the documents. Measuring satisfaction instead of task success. Users rate AI features highly because they are polite. Measure whether the task completed, and whether people returned. Budgeting no operating cost. Build a model of cost per request at launch volume, and know which lever you would pull first if it exceeds your margin. And skipping the human review path. A workflow that cannot be corrected by a person will accumulate errors that nobody notices until a customer does.
“Build a business application with AI inside it—not an AI demo hoping for users.”
AI application build checklist
- ✓Is the AI layer replaceable rather than tightly coupled?
- ✓Are AI-specific UX states designed for uncertainty and citations?
- ✓Is evaluation planned for quality, safety, latency, and cost?
- ✓Is the MVP the smallest end-to-end workflow?
- ✓Are security, monitoring, and analytics included for production?
- ✓Does the roadmap include iteration from real usage?
01
Design the whole system.
Frontend, APIs, data, AI orchestration, and monitoring must be planned as one architecture.
02
Keep the AI layer swappable.
Model providers change quickly; don't couple the whole product to one model.
03
Start from the workflow.
A production application with AI inside beats a standalone AI demo.
Written by
Vordx TeamAI & Software Engineering Team
The Vordx Technologies engineering team builds AI systems, web platforms, and digital products for startups and enterprises. We write about the architecture, cost, and delivery decisions that determine whether a software project actually ships, drawing on production work across AI development, backend systems, and product design.
Planning an AI build?
Vordx ships AI MVPs in 4–8 weeks with fixed scope. See how we scope, price, and deliver production AI systems.
Explore AI engineeringRead next
More field notes from the Vordx studio.
Build with Vordx
Ready to create a digital product that feels impossible to ignore?
Bring us the idea, product, workflow, or brand moment. We will shape it into a premium experience built to launch, scale, and convert.
contact@vordx.com